Isaac Lab factory
Train a Franka arm to lift a cube with RL at 4096 parallel environments, and measure what rendering actually costs.
Weeks 2–3 · RTX 5090 workstation · $0 extra · 02_isaac_factory/
Goal
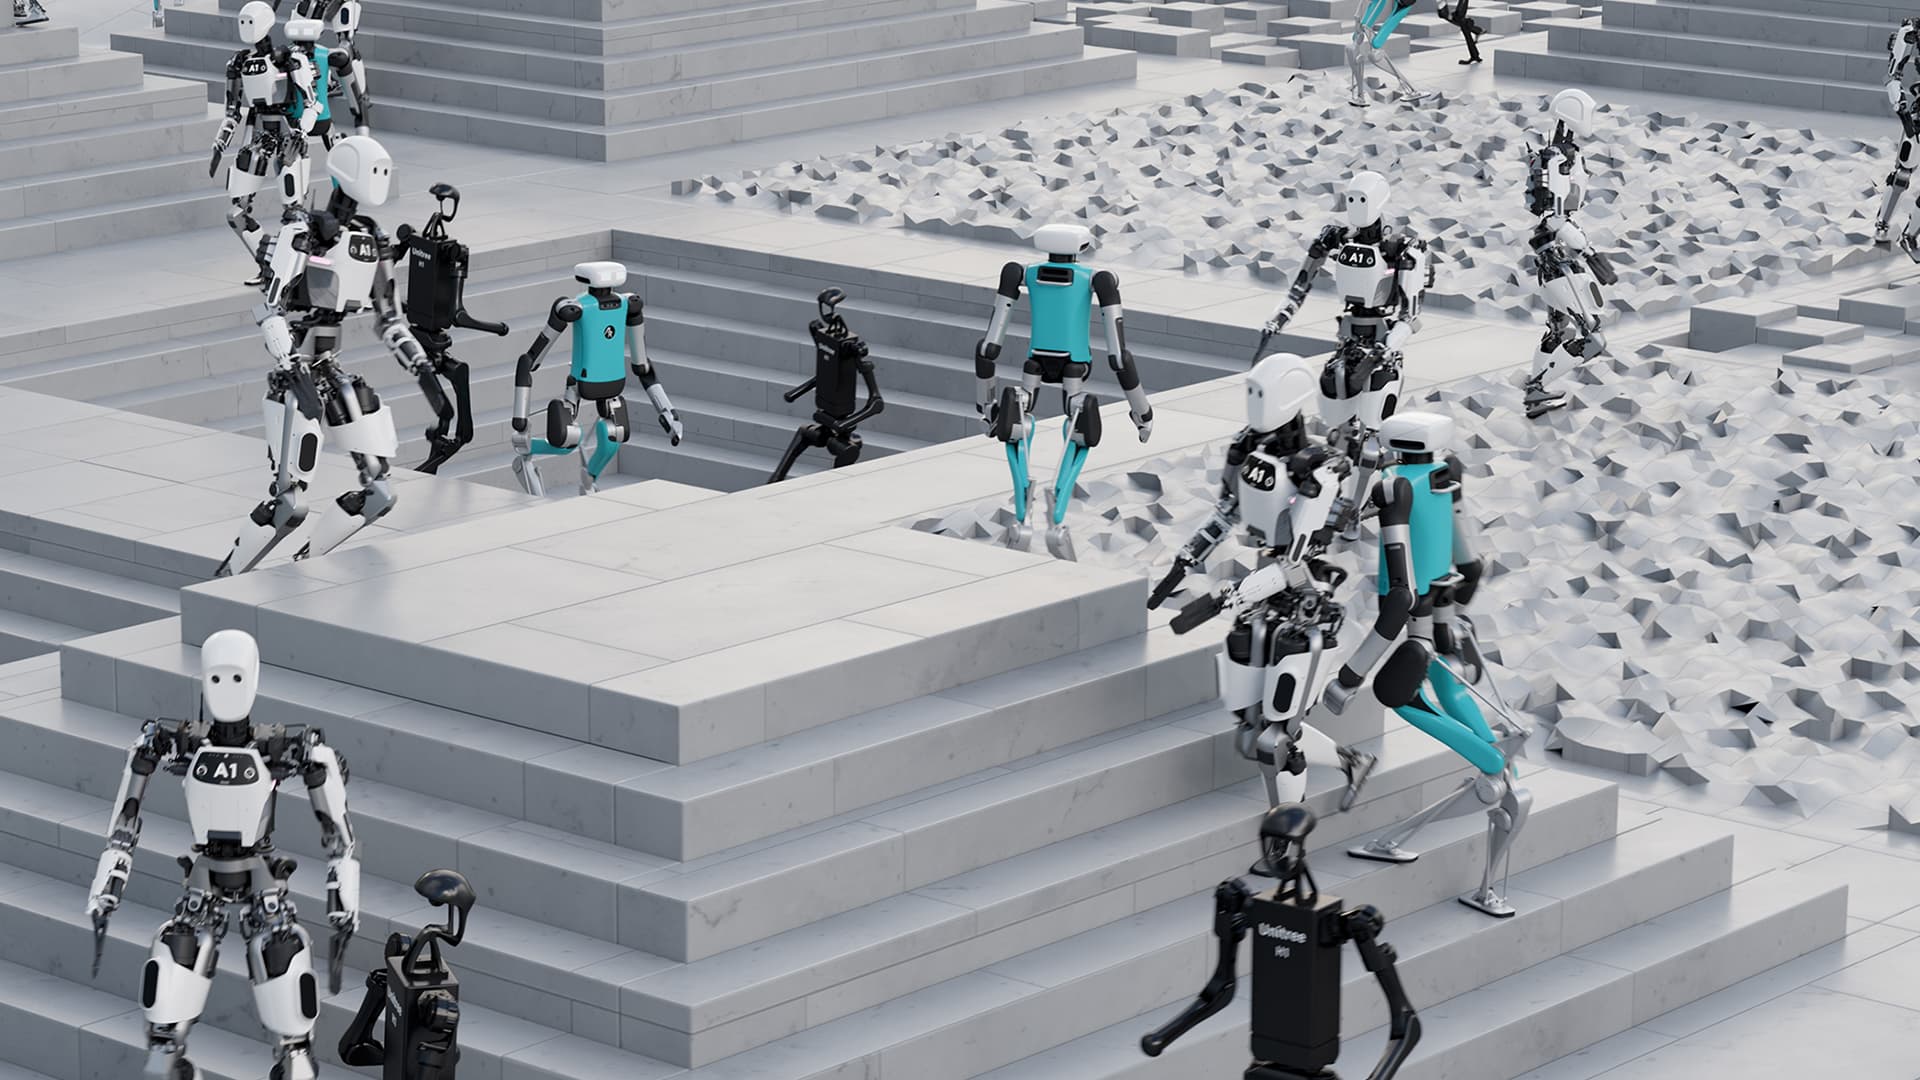
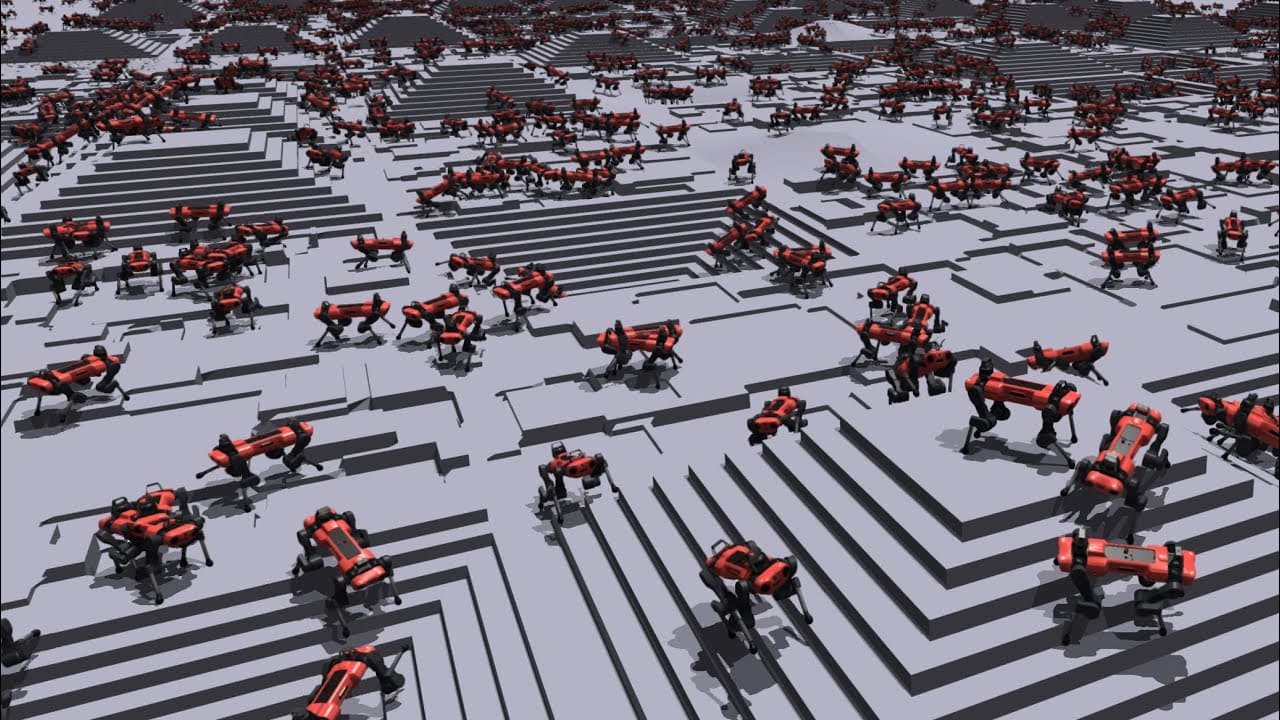
Cartpole is a smoke test, not the project. Stand up Isaac-Lift-Cube-Franka-v0. First confirm Blackwell sm_120: torch.cuda.get_device_capability() must print (12, 0), then a large GEMM TFLOPS number. Smoke any stock task for five minutes, then drop it. Use Isaac-Reach-Franka-v0 as the stepping stone. Then run Lift-Cube headless at 4096 envs to convergence. Record steps/sec, wall-clock, GPU utilization, VRAM. Replay the same run headful and record the throughput drop. Change one reward term, retrain, compare on the same held-out initial conditions.
Why it matters
Contact-rich manipulation is where parallel sim earns its keep, and you can watch it. It also sets up the comparison that matters later: in P4 you teach a real arm a similar task with about 50 demos in under an hour, versus tens of millions of simulated steps and a hand-crafted reward here. “When do you reach for RL and when for imitation?” is a question people ask. This project gives you your own numbers. Isaac Lab already has an env API. A ROS bridge would only slow training.
The work
- 01
Setup gate: get_device_capability() → (12, 0). Record GEMM TFLOPS. Python 3.11 only (3.10 is Isaac 4.x; 3.12 will not resolve).
- 02
Five-minute smoke on any stock task. Then never mention it again.
- 03
Isaac-Reach-Franka-v0 as the easy half of lifting.
- 04
Isaac-Lift-Cube-Franka-v0, headless, 4096 envs, to convergence. Record steps/sec, wall-clock, util, VRAM.
- 05
Same job headful. Record how far throughput drops. Train headless overnight; replay checkpoints headful for clips.
- 06
Change one reward term (grasp bonus, lift height, or action penalty). Retrain. Compare on the same 50 held-out initial conditions.
Done looks like
- p2/SETUP.md with exact versions and one-command install.
- Committed output of get_device_capability() showing (12, 0) and a GEMM TFLOPS number.
- Benchmark table: envs (256 / 1024 / 4096) × steps-per-second, headless vs headful, headful penalty as a percentage.
- A trained Lift-Cube policy with a headful replay video of the arm picking up the cube.
- One reward-shaping A/B with both policies evaluated on the same 50 held-out initial conditions.
- A written note: when Isaac Lab, when MuJoCo. Answered from this run, not the docs.
Stack card
| Simulator | Isaac Sim 5.x / Isaac Lab 2.x |
|---|---|
| Trains on | RTX 5090 |
| Runs on | RTX 5090 |
| Buy | $0 (assumes the 5090 box is up) |
| ROS 2 | No |
| Gazebo | No |
| Compute / target | None |
| Install | Ubuntu 22.04/24.04, NVIDIA driver 580+, CUDA 12.8, PyTorch ≥2.7.0 cu128, Python 3.11, Isaac Sim 5.x (pip), Isaac Lab 2.x, RSL-RL; LeRobot pre-staged for P3 |
Repos to study
Watch out
- PyTorch older than 2.7.0 either throws “no kernel image” on sm_120 or silently wastes the card.
- Do not add a ROS 2 bridge. Isaac Lab already vectorizes the env.
Workstreams
Install, capability gate, Reach then Lift-Cube at 4096 envs, headless training.
Throughput table, headful penalty, reward A/B on 50 held-out inits, when-Isaac-vs-MuJoCo note.
Cross-check. Eval stream can replay the checkpoint headful from SETUP.md alone.
What this proves
You can stand up the hard stack on current-generation hardware, you understand the physics/rendering split, and you measure throughput instead of guessing.
Stand up the hard stack on current-generation hardware, understand the physics/rendering split, and measure throughput instead of guessing.
Study videos
Gear / BOM